Give an AI agent a tool that checks on something slow, like a build, a deploy, or an export, and it will check. Then it will check again, and again, like a kid in the back seat asking “are we there yet?” every few miles.
That sounds harmless until you look at what each question costs. Every check is a full model inference: the whole conversation re-read, a decision made, a tool call emitted, all to learn that nothing has changed yet.
We caught the AI assistant in the Zuplo Portal doing exactly this, and it was following our instructions to the letter. The fix didn’t involve the model at all.
- Building tools for an AI agent, over MCP or plain function calling
- Wrapping something slow in a tool: builds, deploys, exports, batch jobs
- Wondering why your agent burns tokens while it waits on something
The problem: a tool that only knows “not yet”
The assistant can edit files in your project. After it saves one, the project rebuilds, and the assistant checks that the build passed before telling you everything is fine.
The tool for that is check-build-status. It used to do one thing: read the
latest build once and return in_progress, success, or failed. The system
prompt handled the rest:
That’s a while loop, written in English, executed by a language model.
Each lap goes through the model. It reads the whole conversation again (system prompt, tool definitions, the config file it just edited, every earlier tool result), decides that yes, it would like to ask again, and emits a tool call. Then the tool makes one HTTP read, which is the only useful work in the whole lap. Prompt caching softens the input cost, but you still pay for latency and output tokens every time around, and each lap is one more chance for the model to get creative instead of waiting.
There was a quieter cost too. The assistant keeps file contents in its context for 10 steps, so it doesn’t lose track of the file it’s editing. A save, poll, read logs, fix, save cycle could run to eight or nine steps, and most of those were polls. The status checks were pushing the actual file out of the model’s memory.
Here are the five rules we now follow for any tool that wraps slow work.
Rule 1: Let the tool own the loop
If the model’s next move is to call the same tool with the same arguments and hope for a different answer, that loop belongs in your code.
check-build-status now polls the build itself, every 5 seconds for up to 90
seconds, and returns as soon as the build succeeds or fails. The model calls it
once.
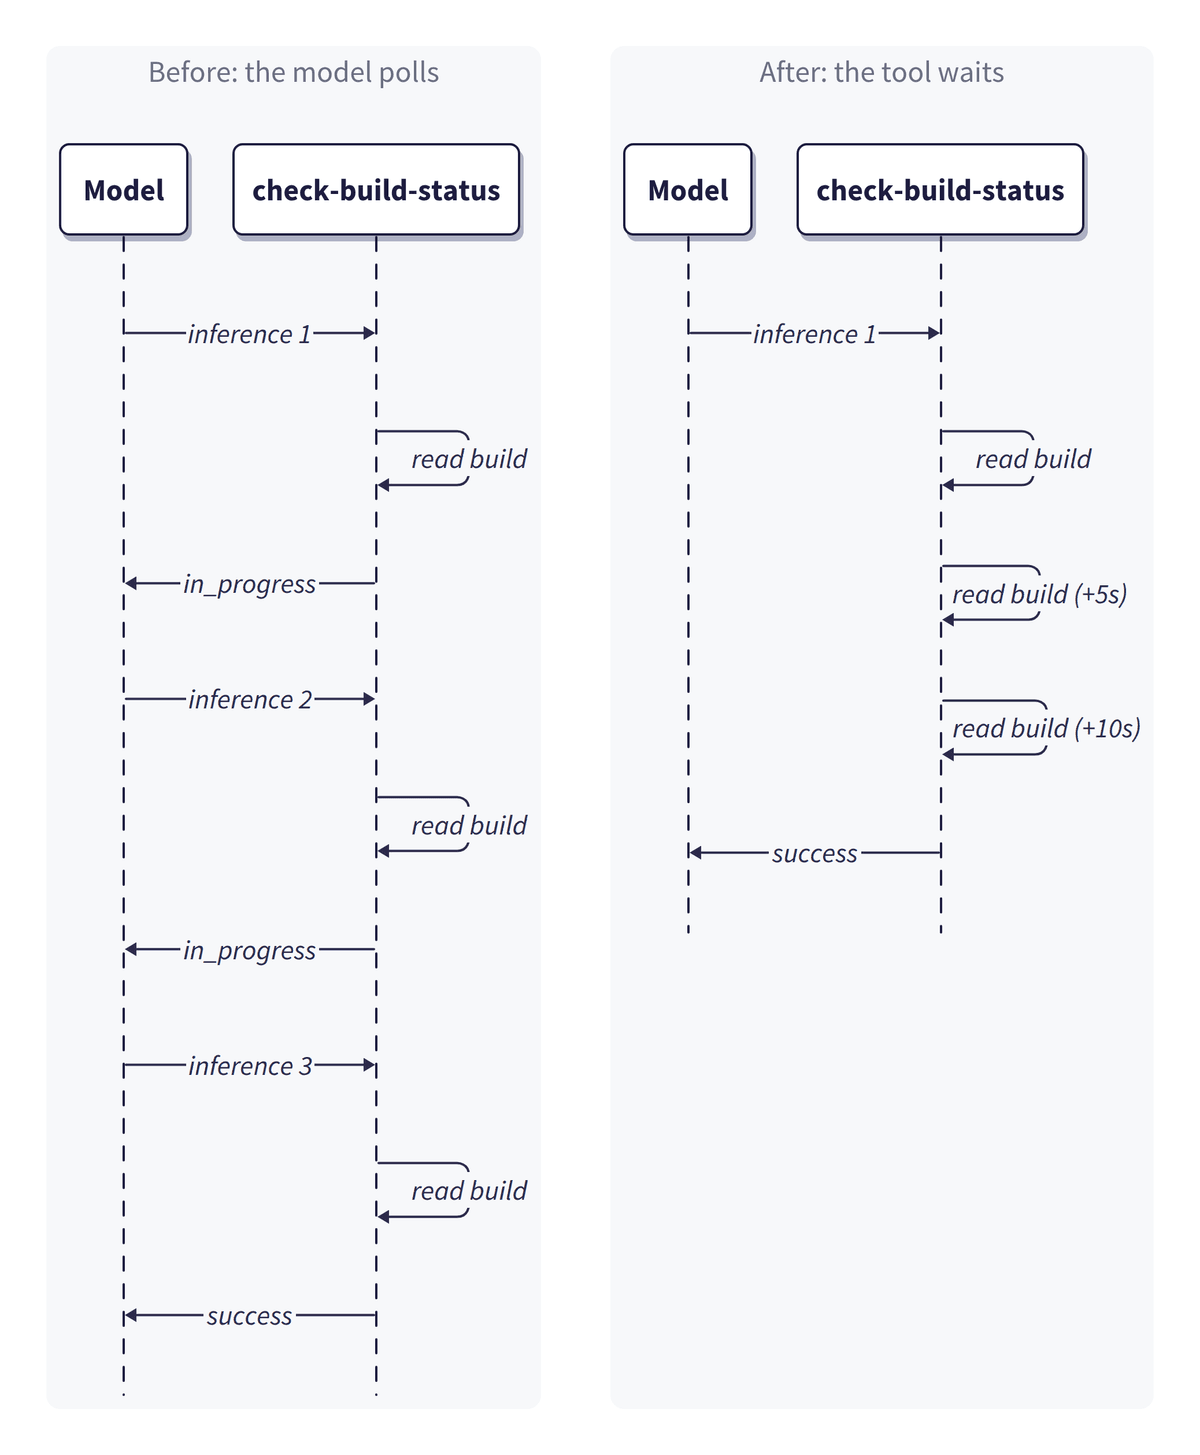
A build wait now costs one inference instead of one per poll. The edit cycle dropped to about five steps, so the same 10-step window keeps the file in context across two full fix cycles instead of one.
Rule 2: Cap the wait below your idle timeout
While a tool runs, the chat stream sends nothing. Plenty of HTTP proxies close a connection after 100 seconds of silence (Cloudflare’s 524 is the famous one), so a tool that waits patiently on a slow build can get the whole conversation cut off underneath it.
That’s why our cap is 90 seconds. Find the shortest idle timeout between your agent and your user, and stay under it.
When the cap hits, return the last state as a normal result. A build still
running at 90 seconds comes back as in_progress, which is an honest answer,
not an error. The model can tell the user it’s still building and call again. A
slow build costs a second inference, which beats a dropped connection.
Rule 3: Make every wait cancellable
If the user stops the turn, the polling has to stop with it.
This is the one we got wrong first. Our initial version passed the request’s abort signal to the pause between reads, but not to the reads themselves, and it only checked the deadline between laps. A slow read, or one that started just before the deadline, could keep the tool running past its 90 seconds and after the user had already hit stop.
The fix was to build one combined signal from the user’s abort and the deadline
with AbortSignal.any(), and pass it to every read and every pause. Now neither
a stopped turn nor the deadline has to wait for an in-flight request to finish.
Rule 4: Tell the model the tool waits
A model follows the instructions it’s given. If the prompt still says “keep calling until it resolves,” it will dutifully poll a tool that already waited.
So the tool’s description went from “Check the latest build status” to “Wait up to 90s for the latest build to finish”, and the keep-calling line in the system prompt became:
Grep for the old instruction before you ship. We found it in two places the model reads, the system prompt and a skill for setting up GraphQL, and both had to change.
What we didn’t change was the tool’s ID. It’s still check-build-status,
because the Portal UI matches tool calls by ID and nothing downstream needed to
know the behavior had changed.
Rule 5: Don’t block on long jobs
Waiting inside the tool fits when the job usually finishes within one bounded
wait. That’s the bet we made for builds, and the in_progress result from Rule
2 covers the ones that don’t.
For work that takes minutes or hours, blocking a tool call is the wrong shape. Return a job ID right away, let the agent tell the user the job started, and pick it back up when something tells you it’s done: a webhook, a notification, a message back into the conversation. That way nobody pays to keep asking a question whose answer hasn’t changed.
The known limitation of our version is the silence. For up to 90 seconds the user sees a spinner and nothing else. Streaming progress from inside the tool would fix that and keep the connection busy at the same time.
A checklist for agent tools that wrap slow work
Before you ship a tool that waits on something, check that:
- The model never has to call it twice in a row with the same arguments.
- The wait is capped below the shortest idle timeout between agent and user.
- Hitting the cap returns the last known state, not an error.
- The cancel signal and the deadline reach every read and every sleep.
- The tool description and the prompt both say the tool waits, and no “keep calling” instruction survives anywhere the model reads.
- Anything that can take minutes returns a job ID and resumes on an event.
The kid in the back seat now naps until we arrive. There’s another option we’ve been eyeing, though: hand the kid a pager. Instead of a tool that waits on the build, the agent subscribes to it, ends its turn, and gets woken up with the result when the build finishes. There’s no open connection, no 90-second cap, and nothing to pay for while it sleeps. That’s a bigger change to how the agent runs than to any single tool, so we’ll save it for another day.
Until then, if you’re writing tools for your own agents on Zuplo’s MCP server, the same rules apply to any custom tool that wraps slow work.