AI Gateway: Cache Pricing, Smart Routing, and New Providers
AI Gateway now accounts for prompt-cache pricing, supports budgets for individual users and customers, and adds Smart Router and Prompt Injection Protection. You can also connect more of your existing cloud models and coding tools, with simpler setup in the Portal.

Cost tracking that accounts for prompt caching
Cost calculations now include cache reads and cache writes for models that support them. Anthropic models distinguish between the 5-minute and 1-hour cache-write rates, and custom models can define their own cache-read and cache-write prices.
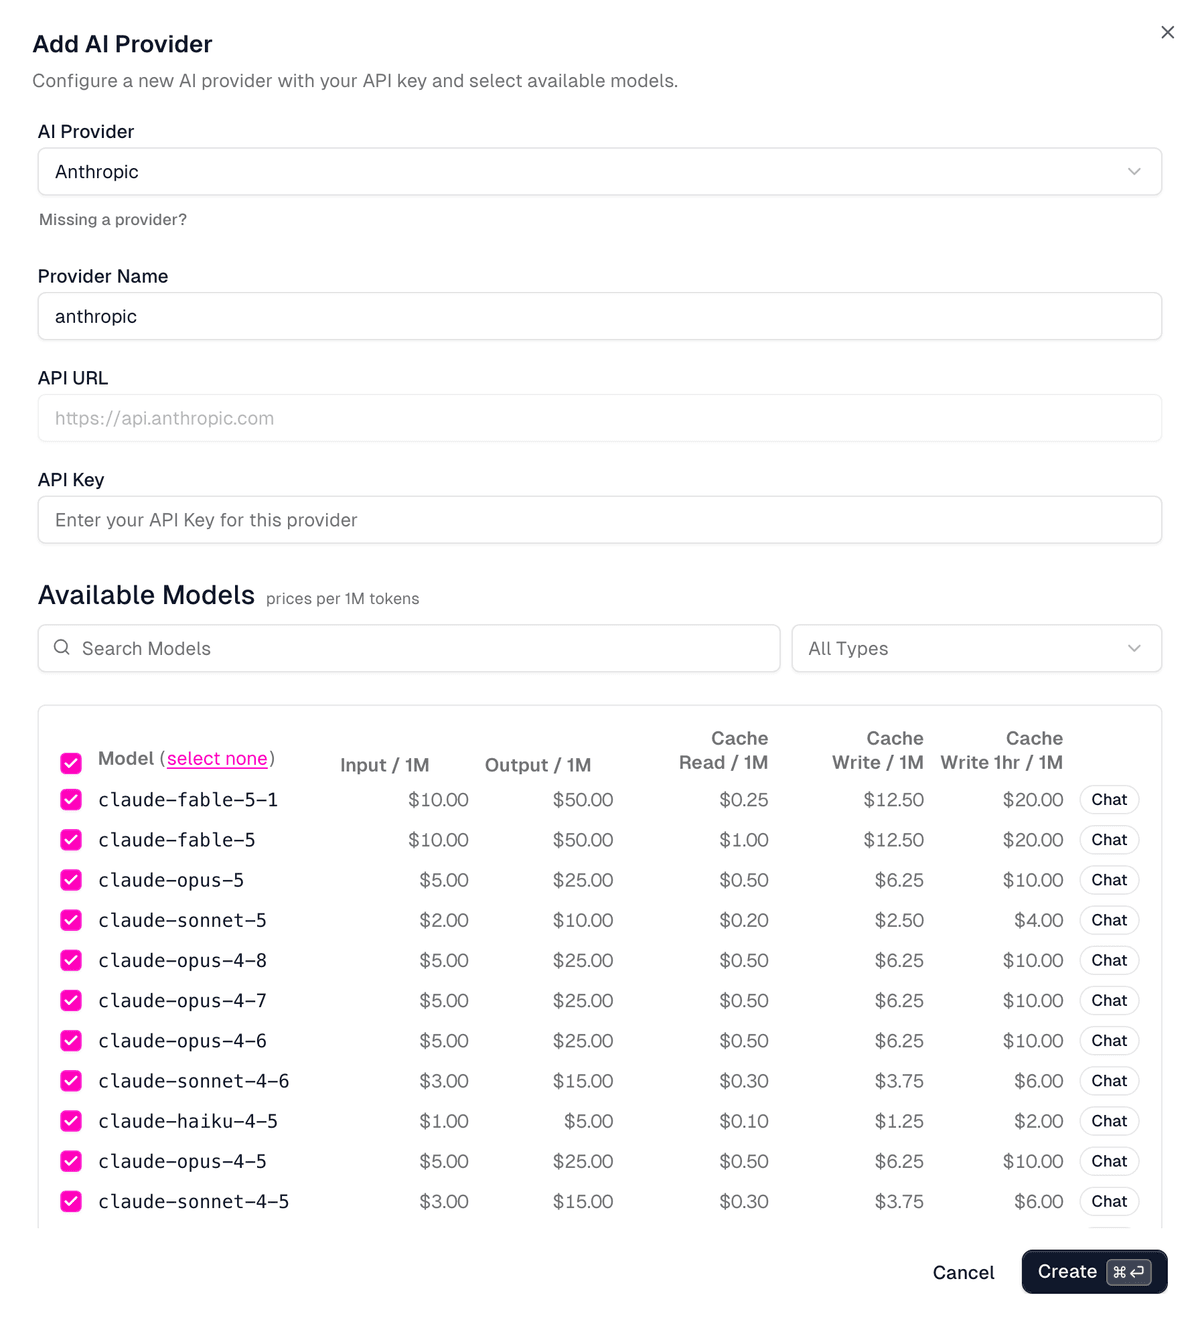
Cost tracking and budgets now use these cache-specific rates. Costs remain estimates based on configured model pricing; provider discounts and other charges can differ from your final bill.
See managing providers for model and pricing configuration.
Budgets for individual users and customers
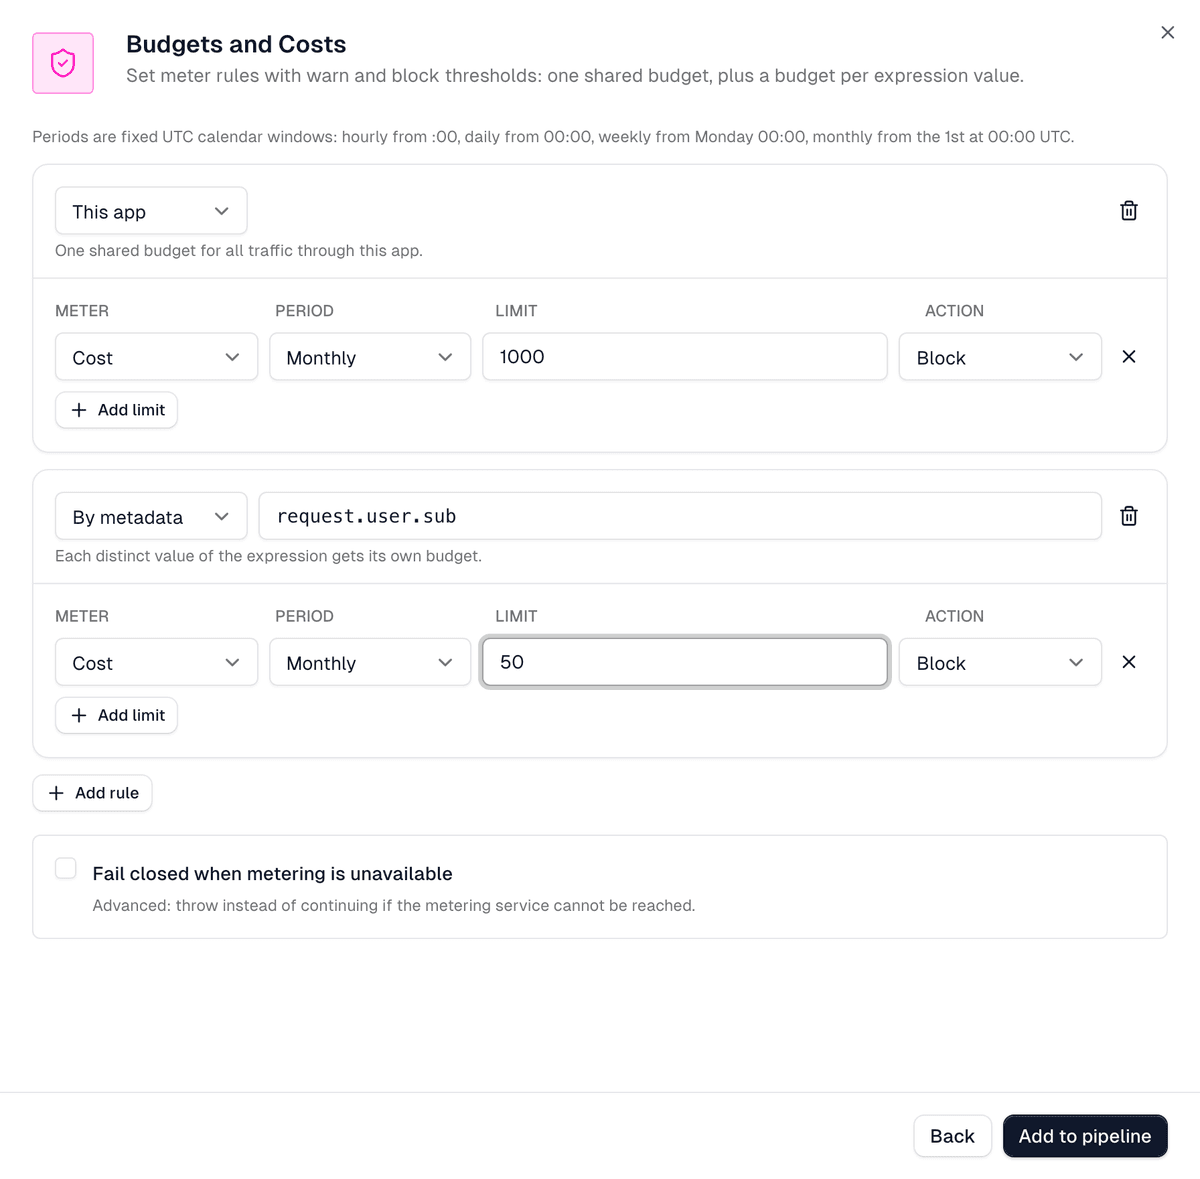
An app can now give each distinct user, customer, or request-metadata value its own cost, token, or request budget. Use authenticated user fields, request headers, or custom context to decide who shares an allowance, and combine those rules with the app’s shared budget.
For per-user enforcement, use an authenticated identity. A caller-controlled header is useful for attribution, but changing its value creates a different budget.
Hourly and weekly periods join daily and monthly budgets. Resets follow the UTC calendar: hourly at the top of the hour, weekly on Monday at midnight. The Portal also shows budget reset and usage-refresh information.
The usage limits guide explains budget rules, reset periods, and accounting delays.
Route requests by prompt complexity
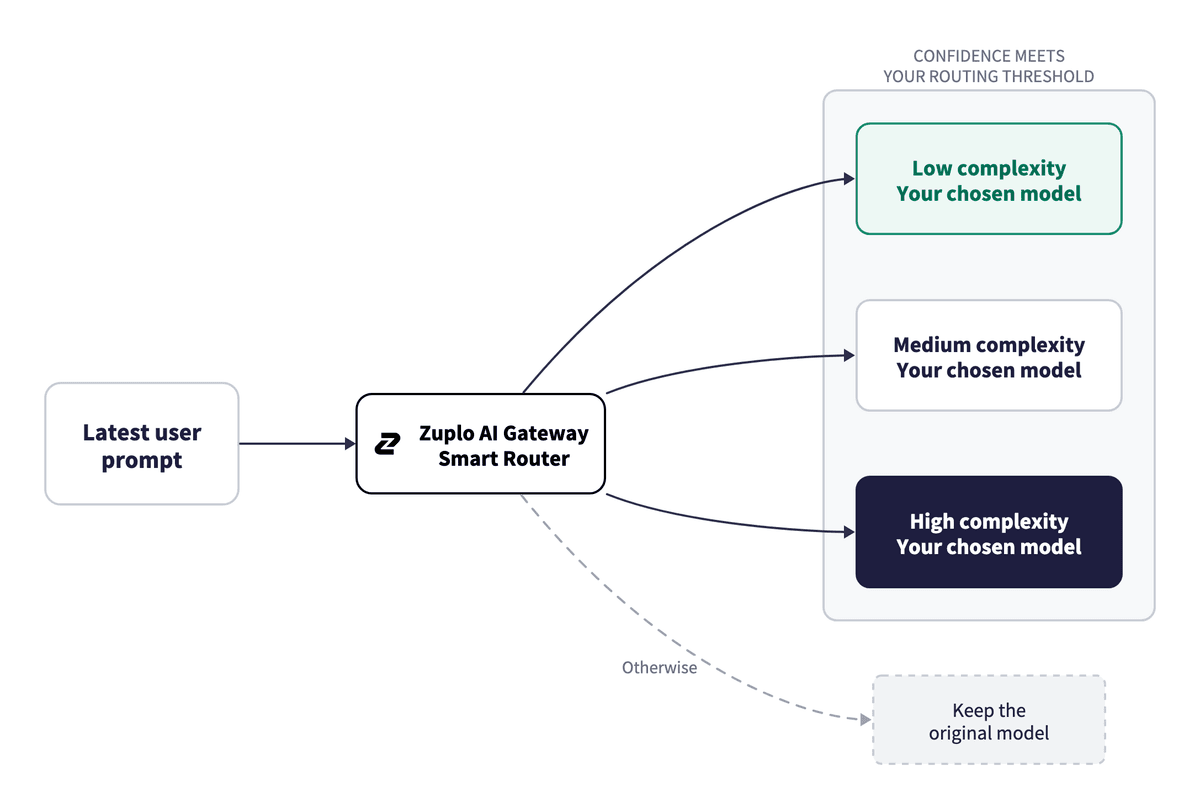
Smart Router classifies the latest user prompt and can route it to the model you choose for low, medium, or high complexity. Set a confidence threshold for routing, or run classification without changing the selected model while you evaluate the results. Custom policies can also read the classification.
The Portal’s policy editor now includes app and model pickers, making it easier to choose the classifier app and the models used for each complexity level. Policy options also accept environment-variable references.
See the Smart Router documentation for configuration and routing behavior.
Screen prompts and tool results for injection attempts
Prompt Injection Protection uses a configurable classifier to screen incoming messages and tool results before forwarding a request to the model. It blocks requests flagged as attempts to override instructions, redefine roles, or manipulate the system prompt.
By default, it inspects the newest message. Increase the inspection window when clients supply conversation history from outside the gateway. Run the classifier through an OpenAI-compatible API or another app on the same gateway; classifier apps can now be restricted to internal gateway calls.
The Data Loss Prevention editor also adds separate inbound and outbound rule controls, custom detectors, streaming options, and a synchronized code view.
Read about Prompt Injection Protection, internal-only apps, and Data Loss Prevention.
Connect models in AWS, Azure, and Google Cloud
- AWS Bedrock Runtime: Use your AWS account through the native Converse and InvokeModel APIs, including their streaming variants. Configure your AWS SDK to call the gateway, which signs upstream requests with your configured AWS credentials. This is separate from Bedrock Mantle’s OpenAI- and Anthropic-compatible endpoints.
- Azure AI: Connect Azure OpenAI and Microsoft Foundry. Map your deployment names to catalog models for cost tracking, use the Responses API with supported deployments, and call Claude through the native Messages API.
- Google Vertex AI: Connect Gemini and embeddings through your Google Cloud project. Claude models are also available through Vertex’s native Anthropic Messages API.
See the setup guides for Bedrock Runtime, Azure AI, and Vertex AI for supported endpoints, models, and credential requirements.
Bring your existing clients and credentials
Credential passthrough lets a caller supply its provider credential while authenticating separately to Zuplo. This supports using Claude Code with your Claude Pro or Max subscription through the gateway. Reported costs use model prices and do not represent your subscription bill.
Client compatibility also expands with endpoint-aware model discovery, Anthropic token counting, and tool calling when translating OpenAI requests to Claude. Custom client headers now reach providers on Chat Completions, embeddings, and Responses requests, with inbound header policies controlling what is forwarded. Gateway credentials and reserved provider headers remain protected.
Follow the Claude Code integration guide for subscription setup, and the Universal API reference for endpoint compatibility.
Getting started
You can now create an AI Gateway and send requests without connecting a repository. Connect source control when you need custom code or want to manage the gateway’s project files in your own repository.
Start with the AI Gateway quickstart, or explore the AI Gateway documentation for providers, apps, budgets, and policies.